Data selection
Selecting which observations to include requires navigating two interrelated concerns: the temporal distribution of acquisitions (Temporal distribution) and the quality criteria for both optical (Optical data selection) and SAR data (SAR data selection). They involve trade-offs that are straightforward to state but difficult to resolve in practice, particularly at global scale.
Temporal distribution
We frame the present discussion around the task of producing a yearly map, a common context, which also requires addressing the challenge of temporal data selection. Under this setting, we discuss how to select EO data in the temporal dimension within a period of approximately 12 months. The conclusions can be extended to shorter or longer windows of time, depending on the nature of the underlying feature being mapped. Furthermore, this framing assumes that multiple temporal acquisitions are available; this might not be the case for high- and very-high-resolution sensors: the Maxar mosaic used by Tolan et al. [1] and the SPOT mosaic underlying Schwartz et al. [2] each rest on a single acquisition per location. Two questions emerge: how observations are represented in time, and what time range they are drawn from.
Regarding representation, the first decision is whether the model sees observations at their original acquisition timestamps, or aggregated onto a fixed temporal grid. Three broad strategies emerge: single time-steps, time-series, or composites, each with its own trade-offs. Time-series are arguably the richest option, capturing phenomena like seasonal variation across a defined period. Pauls et al. [3] showed that a one-year time-series made of the least cloudy Sentinel-2 observation per month preserved the seasonal nuances and geolocation shifts that median composites tend to wash away, and Dixon et al. [4] found benefits in using a time-series of composited PlanetScope imagery over using a single image. The trade-off is data size and model capacity: they are memory-intensive to store by nature, and require a model handling temporal patterns. Furthermore, for each timestep in the time series comes the question of which observation to choose. In the case of optical data, most researchers opt for a time-series with a monthly temporal resolution, choosing the least cloudy product per month [3], [5], [6], [7]. However, a pixel in the tropics and a pixel at high latitude will have different numbers of usable observations, depending on local weather patterns, so the model should be resilient to variable-length, irregularly spaced inputs. In some regions of the world, land observations of certain areas could be consistently underrepresented due to consistent high cloud coverage spanning across the same season over multiple years. Composites offer a pragmatic alternative, distilling an entire period of observations into the memory footprint of a single time-step, as in [8], [9], [10], [11], [12], [13]. Yet, compositing is not without its own costs: it requires deliberate design choices and non-trivial computations. Typical approaches consist of performing mean or median compositing, the latter involving computing percentiles, and the former being more sensitive to outliers. Moreover, if compositing cannot be performed on-the-fly before downloading the data, practitioners must store (at least temporarily) the time-series the composite will be computed from, undermining much of the storage advantage. While the per-pixel processing cost may appear modest in isolation, it scales dramatically: at a global scale, every additional step must be applied to each pixel on Earth, which can quickly become too costly in many settings. One can also produce a time series of composites, e.g., monthly composites of Sentinel-2 [6], seasonal composites [14], [15], [16], [17], or using a predetermined moving window [4], [18], [19], [20]. Using single time-steps, by contrast, is the most cost-efficient route but comes at the expense of the temporal dimension, which often carries rich, discriminative information. Indeed, Mosig et al. [20] found that performance steadily improved with access to longer input timespans when mapping tree mortality, and Boudras et al. [21] found similar results for canopy height mapping. The consequences of this choice will be felt at every subsequent stage: dataset construction, where samples may or may not share a common shape; model design, where the architecture must be able to represent whatever sampling was chosen; and inference, where every pixel on Earth has to be served the same input structure.
Beyond the choice of temporal representation, the time range itself must be defined. Here, we focus on vegetation-related tasks, for which the trade-offs are particularly well documented, but the same considerations apply across domains. A common default is to restrict the analysis to the leaf-on season [7], [8], [20], [22], [23], [24], but identifying that period for every pixel on Earth is in itself non-trivial. Operational phenology products offer one solution: Mosig et al. [20] use the VIIRS Global Land Surface Phenology product [25], while Liu et al. [23] use the MODIS equivalent [26]. Both products are released at annual intervals, so inter-annual shifts in phenological dates are in principle captured. However, the underlying algorithms assume a vegetation cycle with at most two growing cycles per year, an assumption that breaks down for multi-cropping systems with more than two cycles. Van Tricht et al. [17] bypass this limitation by relying on global crop calendars instead [27], [28]. More fundamentally, the annual leaf-on/leaf-off framing is itself a temperate-zone assumption that does not generalize to tropical systems [29]. The leaf-on framing can also be limiting in its own right: Pauls et al. [3] show that incorporating both summer leaf-on and winter leaf-off observations improves performance, and Karaman et al. [30] find that for biomass estimation in Finland, early-spring Sentinel-2 acquisitions are more informative than summer ones, which they attribute to “the higher contrast between vegetation and snow, which enhances the ability to distinguish vegetation properties”. This logic does not extend everywhere, but regions with strong seasonal contrast can benefit from year-round data. A more task-specific variant samples contrasting images from different times within the same year to expose intra-annual variation, as applied by Kerner et al. [31] for crop field segmentation. The calendar year itself is also a poor natural boundary: for example, in the Southern Hemisphere, summer spans the end of one year and the beginning of the next, so a global-scale pipeline must accommodate such cross-year shifts rather than assume that a single calendar year is a sufficient window. Practitioners therefore need to decide how to balance a simple, globally consistent temporal definition against locally appropriate temporal characterization of the modeled phenomenon.
Optical data selection
Even after temporal selection, individual observations vary in usability. Two factors dominate optical imagery: cloud contamination and sensor-specific artifacts that introduce gaps or duplications. Rather than discussing the per-pixel quality flags shipped with each product (e.g., the Sentinel-2 SCL band or Landsat QA band), we focus on higher-level quality criteria that govern whether entire products should be included or discarded.
Upon selecting which data product to work with, a common filter in optical imagery is the cloud cover. In the deep learning literature, whether clouds require explicit treatment at all is debated [32], [33], [34]. We argue that this debate, however, does not extend to scene-level selection: a largely obscured acquisition contributes few valid pixels while incurring the full storage cost; filtering acquisitions based on cloud-cover is therefore primarily a question of dataset economy rather than of model robustness. We elaborate on the various methods to perform cloud detection in Data preprocessing and henceforth assume access to a reliable cloud mask. A common approach is to discard data products with a cloud cover above a certain threshold (e.g., 10% in [8], 35% in [35], 60% in [14], 75% in [36], 90% in [31]). However, for regions with persistent cloud cover, naively filtering out entire data products based on their cloud cover percentage induces the risk of throwing away valuable non-cloudy pixels. For example, when compositing, products with high cloud cover may contain cloud-free areas that fill critical gaps in the composite. Alternatives to thresholding differ mainly in the granularity at which they operate. Per-pixel approaches such as Best Available Pixel (BAP) [37], [38] score every observation independently and retain the highest-scoring one at each pixel, so a clear pixel is kept regardless of its parent product’s overall cloud fraction. Product-level approaches instead select a subset of acquisitions: for example, Muhawenayo et al. [36] designed a Sentinel-2 product selection algorithm where products are chosen based on their contribution of valid pixels to under-represented spatial regions within a tile. Which granularity is practical depends in part on where compositing happens. When it can be pushed to the data provider, per-pixel selection is cheap, since rejected observations are never transferred. When data must be retrieved locally, per-pixel scoring requires downloading every candidate acquisition and discarding most of it; selecting a small subset of products becomes the only tractable option. A similar constraint applies to the masks themselves: computing or accessing a cloud mask at the stage of data product selection can be computationally expensive, since it must be done for each candidate product. Most optical data providers report cloud cover statistics in their products metadata, which explains the persistence of scene-level thresholding, despite its known failure mode.
Another important criterion for selecting optical data products is the occurrence of artifacts. For example, Landsat 7 imagery acquired after 2003 exhibits wedge-shaped gaps from the Scan Line Corrector failure, affecting roughly 22% of each scene [39], [40]. More generally, a subtler problem arises when the distribution unit of a product is not aligned with its acquisition unit. Sentinel-2 is the clearest example: the granule is a fixed tile, while the sampling unit is the orbit. Consequently, a tile may be covered partially by one orbit and fully by another, may require mosaicking several orbits acquired on different days, or be affected by other subtle failure cases. Appendix: Identifying Sentinel-2 tiling artifacts illustrates such cases. Addressing these issues is important to avoid duplication of pixel values, which would bias any statistics computed over the data — whether during compositing or when calculating overall dataset statistics from, for example, all Sentinel-2 products acquired within a given time frame, as in [41], [42].
SAR data selection
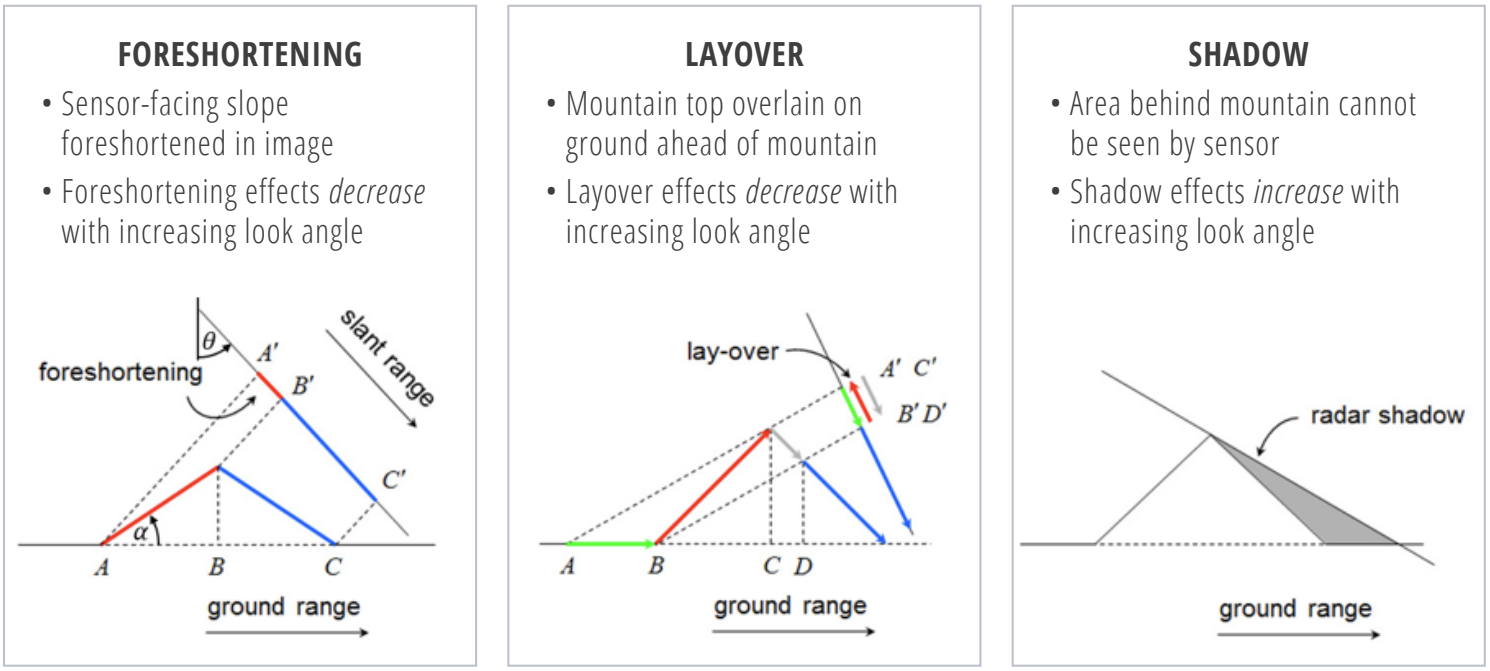
SAR imagery is not affected by clouds, but its side-looking acquisition geometry introduces its own artifacts: geometric distortion due to foreshortening, layover, and shadow (see Figure 4.1). These deterministic perturbations arise from the interaction between terrain relief and the radar’s look vector: given a digital elevation model and the acquisition geometry, the distortion pattern can be predicted. This predictability is useful at the selection stage: the sheer data volume and the need for geometric consistency over time argue for working with a subset of the data. Since the distortion associated with each candidate geometry can be computed in advance, that subset can be chosen analytically, before any data is downloaded. Appendix: Selecting a SAR viewing geometry gives an example of this procedure for Sentinel-1.
Another common choice is that of the pass direction. While some regions (among them large portions of Africa, Australia, Russia, Canada and the eastern Americas) are systematically acquired in a single pass direction [43], when both ascending and descending acquisitions of the same area are available, they can be complementary. They should not, however, be treated interchangeably: unless corrected, the azimuthal dependency of \(\sigma^0\) can cause major problems when comparing images acquired from ascending and descending passes [44]. This has a direct impact on model design: global coverage favors models that accept missing modalities (see Model design and training) over ones that assume a complete and fixed input stack.